Under a second,
every single turn.
Most 'voice AI' is a chatbot with text-to-speech stapled on. TwoPeas is voice-to-voice end to end — your audio streams to the model, the model streams back, and the conversation flows like a phone call.


The shape of this companion
Audio streams continuously. The model starts responding while you're still finishing your sentence.
Barge in. Pause. Think out loud. The voice pipeline handles all of it without breaking the moment.
Soft, bright, husky, deep — tuned for warmth, not newsreader polish. More coming.
The old way: record your audio, upload it, wait for a transcript, run the transcript through a language model, generate a reply, run the reply through a TTS voice, stream that back. Four hops and three network round-trips. The result feels like a walkie-talkie.
The new way: bidirectional audio streams over a single WebRTC connection. The model hears you as you speak, starts composing a reply while you’re mid-sentence, and begins speaking back within a few hundred milliseconds of you finishing. That’s the difference between a voicemail exchange and a conversation.
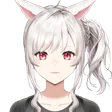
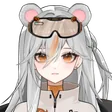
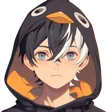
We pair it with a Live2D avatar that lip-syncs in real time and expresses seventeen distinct emotions — picked by the model itself based on what’s happening in the conversation. The result is presence, not parsing.
Voice AI — chat-with-TTS vs voice-to-voice
| Feature | TwoPeas | Others |
|---|---|---|
| Response latency | Sub-second (WebRTC) | 2–5 seconds (HTTP + TTS) |
| Barge-in support | Yes — interrupt any time | Rarely; breaks mid-response |
| Turn-taking feel | Conversational | Walkie-talkie |
| Face + expression | 17 emotions, lip-synced | Static or none |
| Memory | Persistent across calls | Usually per-session only |
Quick answers
How low can you get the latency?
Under 1 second end-to-end on a decent connection. Most responses start inside 400ms of you finishing your sentence.
What's the voice model?
We use a realtime voice model provider under the hood. The shape of the pipeline is what makes it feel natural, not the specific model.
Does it work on mobile?
Yes. WebRTC works in Safari, Chrome, and Firefox on iOS and Android. No app to install.
Do you support custom voices?
Not yet — we ship four hand-tuned presets. Voice cloning is on the roadmap with strict consent gating.
What's the bandwidth requirement?
About 1 Mbps up/down. It works on 4G and Wi-Fi; it degrades gracefully on weak connections.